How Dynamic Dialects checks it What enterprise buyers need from tech, and how Dynamic Dialects delivers it.
Dynamic Dialects confirms the product or platform, the content type, the target markets, the technical constraints, and the delivery owner before production starts. That keeps localization, transcription, annotation, and support content aligned with the release, not scheduled as a separate language-team workstream that the product team then has to reconcile before shipping.
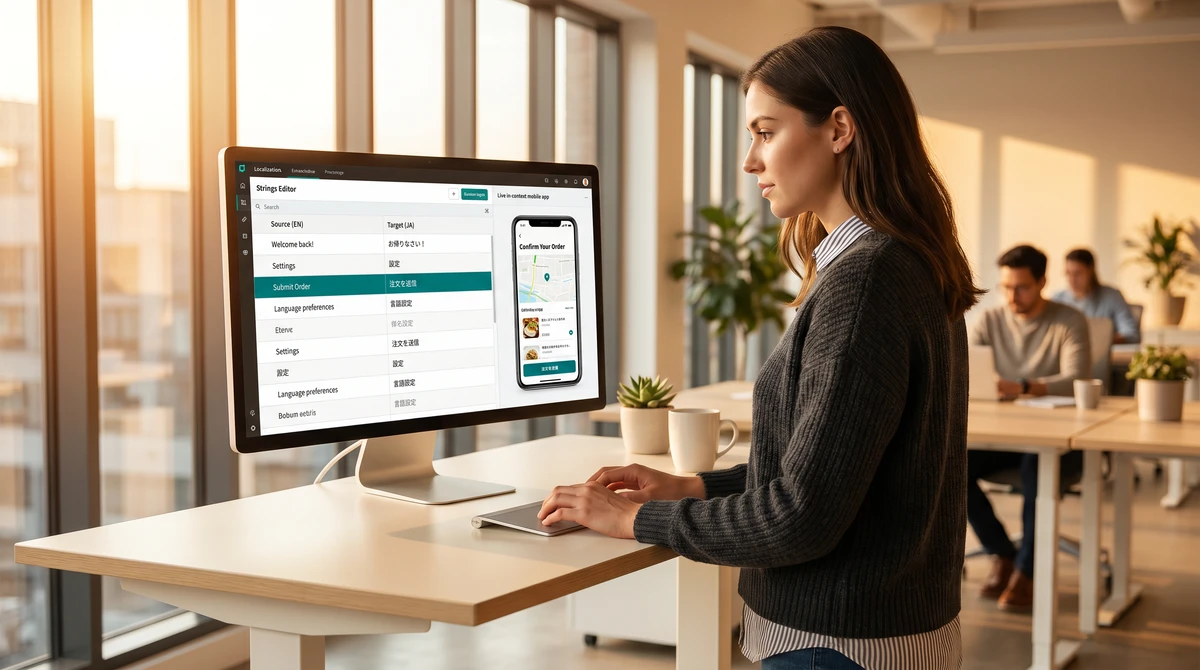
Product and software localization requires technical context that word-for-word translation bypasses. UI strings have character limits that expansion into the target language may exceed. Dropdown labels must fit the interface at the target locale's script. Error messages must reflect the product's actual behavior in the market, not a literal translation of the English error state. Help content must reflect the market-specific user flow, not the English flow with foreign words substituted. Dynamic Dialects reviews screenshots, UI constraints, character limits, and product context before translation begins so the localized output fits the interface the user will actually see.
Support knowledge base and customer-facing content programs need an agreed update cadence. Ask which source changes trigger localized updates, which locales are active, who approves terminology, and when revised pages are due. Dynamic Dialects can propose rolling delivery, contact continuity, and a terminology record for the program.
User research and qualitative data localization sits between interpretation and annotation. Session recordings, interview clips, usability test transcripts, and multilingual feedback need transcription output that reflects the actual speaker, the language context, and the downstream use, not a generic clean-read transcript. For research clips feeding an AI annotation pipeline, the schema, label format, and language flags must match the pipeline spec. Dynamic Dialects scopes research transcription and annotation against the downstream use when the project is reviewed, not after the first batch reveals a mismatch.
AI and ML product companies operating with multilingual data programs are covered under the AI/ML industry entry point, but technology companies with translation-adjacent data needs (multilingual app store optimization, product-catalog localization, marketing translation, technical documentation) fit here. Dynamic Dialects structures each project around the product owner, the release date, and the content type, not around a service catalog the product team must sort through before sending a request.