Need a certified translation? USCIS · legal · medical · academic (407) 537-2522 Explore services →
Solution · Transcription

Send audio and get back a transcript your team can actually use.

DD scopes transcripts for the way your team will use the recording. Agree languages, clean-read or verbatim style, speaker labels, timestamps, output format, and recording access before production starts.

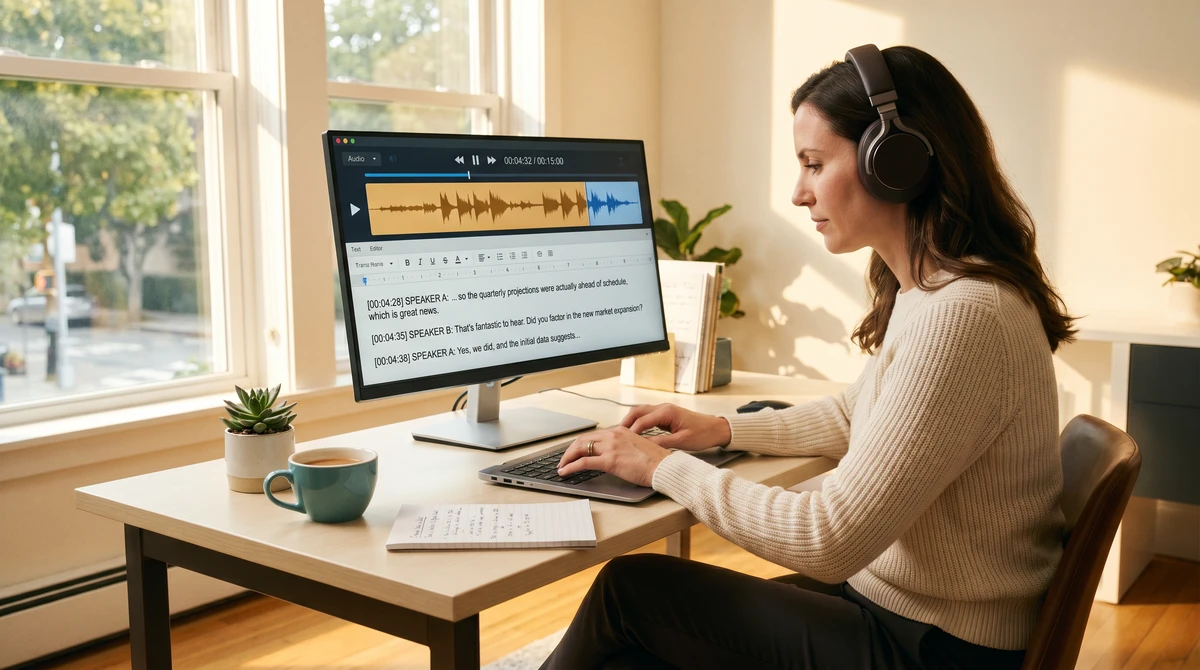
Illustration of a transcriptionist with headphones in a bright office working in transcription software showing a waveform and a timestamped transcript
250+ Languages
40,000+ Vetted linguists
Review plan Agree for your project
Contact Name in the written scope
Evidence for review

What DD can show before a buyer commits.

This is not a public case study claim. It is DD-owned evidence a buyer can request when the work needs vendor review before a scope is approved.

Ask for proof details
Review the request and evidence details
Buyer type
Transcription buyer, program owner, or language-company operations lead qualifying DD before sending production files.
Problem
The buyer needs transcription scoped by work type, languages, inputs, deadline, and review process before a quote is accepted.
Scope
Transcription with a proposed coordination contact, review roles, and written terms confirmed for the project.
Constraint
No public DD case study is cleared for this service yet, so proof must use DD-owned process artifacts instead of borrowed claims.
DD action
Agree the transcription scope, coordination contact, production and review roles, and written next steps before work begins.
Evidence available
Private proof can include a service start checklist, redacted QA summary format, delivery record format, and sourcing or staffing notes.
Outcome
The buyer can validate fit and operating discipline before sending production files or adding DD to a vendor roster.
Disclosure status
DD-owned proof only. Public client outcomes require approval; redacted process artifacts can be shared when disclosure terms allow.

How DD checks it

What enterprise buyers need from transcription — and how DD delivers it.

DD confirms transcription scope before production: language, speaker count, audio quality, transcript style (clean-read, verbatim, timecoded, speaker-diarized), output format, and the downstream use - whether the file feeds captions, legal reference, research review, or an AI data pipeline. That scope review prevents a research file, legal recording, training clip, or model dataset from receiving a transcript style that does not match its intended use.

The output style is determined by use, not assumed from the file type. A clean-read transcript removes filler and false starts for readability. A verbatim transcript preserves every utterance for legal or research accuracy. A timecoded transcript anchors text to the audio for caption production or review. A speaker-diarized transcript attributes turns to named or labeled participants. DD confirms which style the downstream workflow requires before production begins.

Audio quality, speaker overlap, background noise, code-switching, dialects, and file length all affect transcription feasibility and effort. DD reviews a sample file at request review - before quoting - to identify these factors. If overlap, noise, or dialect creates a risk for accuracy, DD flags it before accepting the project and states what the accuracy expectation can realistically be for that audio.

For AI data pipelines: transcription output can be scoped to match the pipeline's schema, label format, and downstream annotation requirements. Speaker labels, timestamps, language flags, and quality notes are formatted to the buyer's specification. Rolling-batch delivery is available for ongoing pipelines - files are received incrementally and returned transcribed on a defined cadence.

For legal, clinical, or government recordings, agree confidentiality terms, authorized listeners, transfer platform, permitted downloads, retention, and evidence of access closure before sending files. Any browser restrictions depend on the chosen platform and project terms.
In the tool

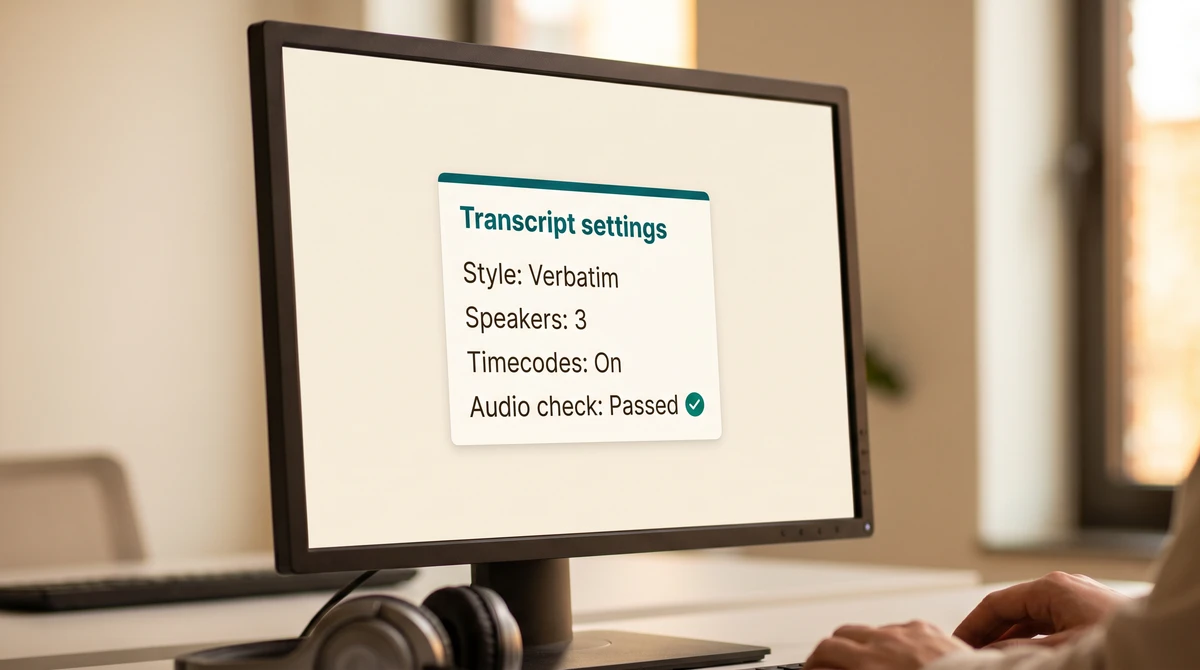
Transcript style and audio quality confirmed before production — not assumed from the file type at delivery.

Illustration of a close-up of a transcript settings card showing style, speaker count, timecodes, and a passed audio quality check

Step by step

  1. Send an audio sample and scope

    Submit an audio or video sample, language, speaker count, recording length, transcript style (clean-read, verbatim, timecoded, or speaker-diarized), output format, and downstream use.

  2. Audio review before quoting

    DD reviews the sample before quoting. If overlap, background noise, dialect, or speaker count creates an accuracy risk, that is flagged before the project is accepted — not discovered mid-production.

  3. Production matched to downstream use

    The transcript style is confirmed against the downstream use: clean-read for readability, verbatim for legal accuracy, timecoded for caption production, speaker-diarized for research review. The right style is confirmed before work begins.

  4. Delivery in the format your workflow needs

    Output is formatted to the downstream specification. For AI data pipelines, schema, speaker labels, timestamps, language flags, and quality notes are matched to the agreed pipeline spec.

Quality and delivery

What to settle for this engagement.

Choose transcript style

Confirm clean-read or verbatim output, timecodes, speaker labels, and receiving format for the intended use.

Sample audio before quoting

Share a representative segment so noise, overlap, dialect, and speaker count can be considered in the proposed scope.

Match AI-data requirements

For dataset work, specify schema, labels, review sample, and the cadence of any staged delivery.

Agree recording controls

Before sending sensitive audio, confirm confidentiality, authorized listeners, transfer platform, downloads, and deletion instructions.

Quality-management controls Information-security controls Confirm the quality and information-security requirements for your project

How this compares

ConsiderationTypical vendorDynamic Dialects
  • Audio quality reviewQuoting based on file length only; quality issues discovered mid-productionSample reviewed before quoting; accuracy risks named before the project is accepted
  • Transcript styleOne default style applied regardless of downstream useClean-read, verbatim, timecoded, or speaker-diarized confirmed against how the output will be used
  • AI pipeline outputGeneric transcript that the data team reformats for the pipelineSchema, label format, and output requirements matched to the pipeline spec at scope review
  • Sensitive recordingsHandling terms left unstatedAgree confidentiality, authorized roles, transfer, and retention before file access
Where this helps

Use this service when the stakes are clear.

  • Audio and video transcription in 250+ languages, including lower-resource and accented recordings
  • Speaker diarization, timestamps, and clean-read or verbatim formats matched to downstream use
  • Transcription for AI data pipelines - schema-matched output, rolling-batch delivery
  • Legal, clinical, and government recordings with agreed confidentiality and access terms
  • Input preparation for caption production, research review, and compliance documentation
What to send first

What to include

  1. Audio or video sample and recording length
  2. Language, speaker count, and any dialect or accent notes
  3. Transcript style - clean-read, verbatim, timecoded, speaker-diarized
  4. Output format and downstream use - captions, AI data, legal reference, research
Upload files for a scope

Send an audio sample, language, speakers, transcript style, and intended use. Ask for written feasibility, contact, and delivery terms.


Questions

Common questions before sending project details.

What transcript styles does DD support?

DD supports clean-read (filler removed, readable), verbatim (every utterance preserved), timecoded (text anchored to the audio timeline), and speaker-diarized (turns attributed to named or labeled participants) transcripts.

How does DD handle multilingual, accented, or code-switched audio?

DD reviews a sample file at request review before quoting. If overlap, background noise, dialect, accent, or code-switching creates an accuracy risk, it is flagged before the project is accepted - not discovered mid-production.

Can DD transcribe audio for AI data pipelines?

Yes. Transcription output can be scoped to match the pipeline's schema, label format, and annotation requirements. Speaker labels, timestamps, language flags, and quality notes are formatted to the buyer's specification.

What data handling controls apply to sensitive recordings?

Before sending sensitive recordings, agree NDA requirements, authorized listeners, transfer method, access end date, and evidence of closure for this engagement.

When do I need timestamps or speaker labels?

Timestamps are needed when the transcript must be traced to the recording - for caption production, legal reference, research review, or AI analysis where text must be anchored to a timecode.

What should a transcription request include?

Send an audio or video sample, language, speaker count, recording length, audio quality notes, transcript style, output format, downstream use, and any schema or label requirements if the transcript feeds an AI pipeline.


Related

Keep moving from the same request.

Dynamic Dialects LLC Mailing address 1317 Edgewater Dr 536 Orlando, FL 32804 (407) 537-2522 info@dynamicdialects.com Mon-Fri | 8a-7p ET
Send the requirement

Get the right scope in writing.

Share the language pair, file type, audience, or problem. DD replies with availability, open questions, handling notes, and the next step before work starts.

Send the five required details to start. Add files later if handling needs review.

For supplier opportunities, visit Vendor onboarding. For jobs, visit Careers.